How to Run Open-Source Software in Production Without a DevOps Team
You do not need Kubernetes or an on-call rotation to run open-source tools reliably. Here is the minimum viable operations setup, what to buy instead of build, and a monthly routine.
There is a belief that running your own software in production requires a DevOps team, a Kubernetes cluster, and a pager. For a small team running a handful of open-source tools, none of that is true. What you need is a short list of habits and the discipline to keep them.
Here is the whole setup.
One server, not a cluster
A single well-chosen virtual machine ($20–$60 per month) runs a surprising amount: an internal wiki, an analytics tool, a status page, a bookmark manager, a small internal app, all at once. Add a second server only when you have a specific reason (redundancy for something that must not go down), not preemptively.
Use Docker Compose to define what runs. One directory, version-controlled:
ops/
  docker-compose.yml    # the reverse proxy
  apps/                 # one compose file per app
  data/                 # every persistent volume, in one place
  backup.sh
  runbook.md
Keeping all state under data/ is what makes backups a single command later.
The five things that make it "production"
1. A reverse proxy with automatic HTTPS. Caddy or Traefik gets you TLS certificates and per-subdomain routing with almost no config. This is the front door for everything.
2. Backups you have restored. A nightly job that dumps databases and pushes an encrypted copy off-site, plus a quarterly restore drill. If you have never restored it, assume it does not work.
3. Monitoring that tells you before users do. You need two alerts at minimum:
- Uptime: an external service pings each public URL every minute and messages you if it fails twice.
- Disk space: a cron check that alerts at 80% full. Disk filling up is the single most common cause of a self-hosted outage.
#!/usr/bin/env bash
# disk-check.sh — run from cron every 15 minutes
USE=$(df --output=pcent / | tail -1 | tr -dc '0-9')
if [ "$USE" -ge 80 ]; then
  curl -s -X POST "$ALERT_WEBHOOK" -d "text=Disk on app-server at ${USE}%"
fi
4. Controlled updates. Run an update-notification tool in monitor-only mode. Once a week, read what changed, then:
docker compose -f apps/wiki.yml pull
docker compose -f apps/wiki.yml up -d
Because data lives outside the container, recreating it is safe.
5. A runbook. A plain Markdown file: how to restart each service, where backups are and how to restore one, what the DNS records are, who the registrar and hosting accounts belong to. Write it for the version of you debugging at 7am, or for whoever covers when you are away.
Buy the hard parts, host the easy parts
Self-hosting is not all-or-nothing. Some things are genuinely specialist, and paying for them is the right call even in a DIY setup:
| Host it yourself | Pay someone |
|---|---|
| Wiki, docs, dashboards | Transactional email delivery |
| Analytics, status page | DNS (use a managed provider) |
| Bookmark/read-later, feed reader | Off-site backup storage (object storage) |
| Internal tools, low-stakes apps | Error tracking at real scale |
| A small database | A large or must-not-lose database (managed Postgres) |
The rule: if getting it wrong means silent data loss or a deliverability black hole, and fixing it is a whole discipline, rent it.
Be honest about uptime
One server with no redundancy realistically gives you "99.9% if you are attentive" — roughly nine hours of downtime a year, often during an update or a reboot. For internal tools and low-stakes services, that is fine. For anything customer-facing where an outage costs real money, either add redundancy (and the complexity that brings) or use a managed host for that specific piece.
Know your tolerance per service. Not everything needs the same reliability.
The monthly routine
About two hours, once a month:
- Check that last night's backup exists and is a plausible size.
- Read the update notifications; apply them one app at a time; click around each app afterward.
docker system pruneto reclaim space from old images.- Skim the uptime monitor's history for blips you missed.
- Apply OS security updates and reboot if the kernel changed.
- Once a quarter, instead of the above: do a full restore drill onto a throwaway server.
When to actually get help
Bring in a contractor or a managed service when: a service becomes business-critical and needs real high availability; you are spending more than a few hours a month firefighting; or you are about to run something operationally heavy (a large database, a search cluster, a mail server) that you do not want to specialize in.
Until then, one server, Docker Compose, HTTPS, tested backups, two alerts, and a runbook will carry a small team a long way.
Related posts
More on Self-Hosting, Operations.
Coolify vs Dokploy vs Arcane vs Openship: The Self-Hosted PaaS Comparison
Real dashboard screenshots, honest pros and cons, and the exact licensing fine print for Coolify, Dokploy, Arcane, Dokku, and Openship — the open-source platforms that replace Heroku, Vercel, and Netlify on your own server.
Reverse Proxy Explained: Caddy vs. Nginx vs. Traefik for People Who Just Want HTTPS
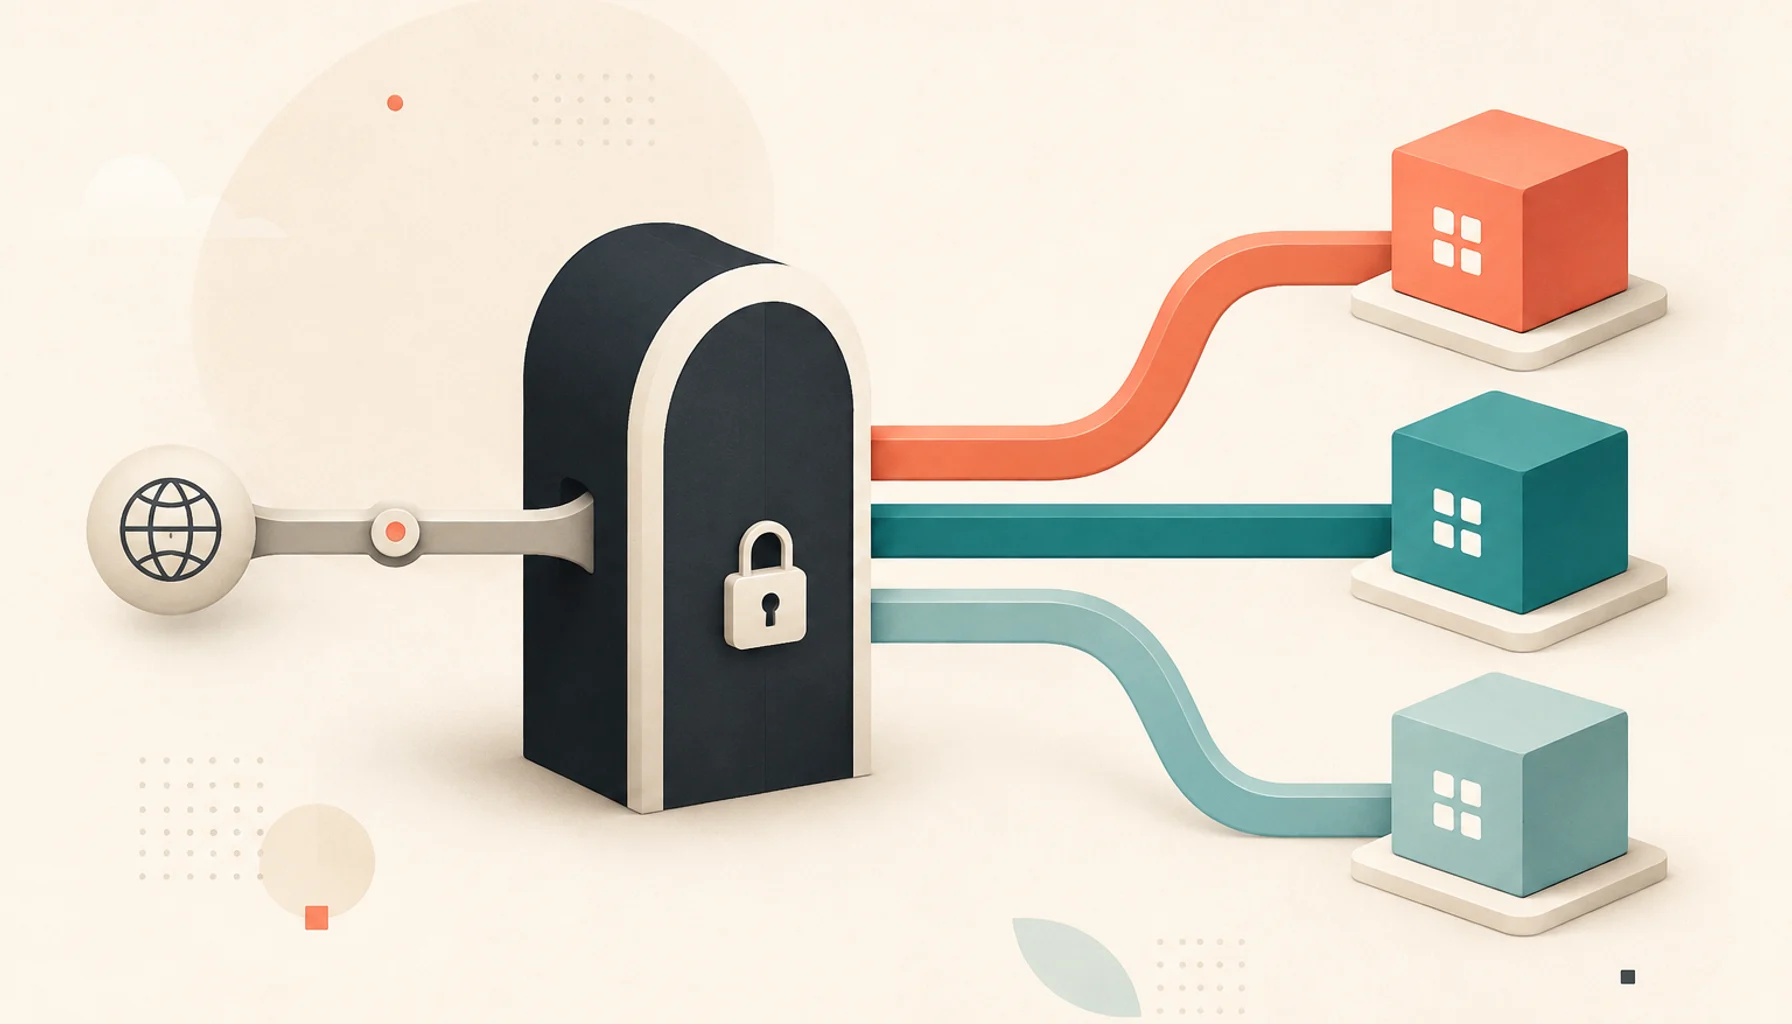
What a reverse proxy does, why every self-hosted setup needs one, and how the same job looks in Caddy, Nginx, and Traefik, with the actual config for each.
PostgreSQL vs. SQLite for Self-Hosted Apps: Which Should You Actually Use?
SQLite is not a toy and Postgres is not always overkill. A practical look at when each one is the right call for a self-hosted app, with concrete scenarios.